Predictive maintenance turns equipment data into an operational decision: intervene before a failure becomes downtime, but not so early that useful asset life is wasted. This guide explains the architecture, AI methods, industrial use cases and implementation choices required to make predictive maintenance work in production.


Industrial maintenance has traditionally operated around two questions:
Has the machine already failed?
or:
Has enough time passed that we should service it anyway?
Predictive maintenance introduces a third:
What does the current condition of the asset tell us about what is likely to happen next?
That difference is fundamental.
Predictive maintenance uses equipment condition, operating context and historical behavior to identify degradation early enough for maintenance teams to act before a disruptive failure occurs.
In modern industrial environments, this can involve vibration, temperature, pressure, current, acoustic emissions, oil analysis, machine states, production conditions, maintenance history and other operational data.
Artificial intelligence and machine learning make it possible to identify patterns that would be difficult to encode manually, but the machine-learning model is only one component of the system.
A production predictive-maintenance system also needs reliable sensor acquisition, asset context, data pipelines, maintenance workflows, alert policies, integration with CMMS or ERP systems, model monitoring and a clear process for converting predictions into maintenance decisions.
What is predictive maintenance?
Predictive maintenance is a maintenance strategy that uses the observed condition and behavior of an asset to estimate when intervention may be required.
Instead of repairing equipment only after failure or servicing every machine according to a fixed calendar, predictive maintenance attempts to detect degradation and estimate risk before the failure becomes operationally disruptive.
The objective is not necessarily to predict the exact second a component will fail.
A useful system may instead answer questions such as:
Is this machine behaving abnormally?
Which component is likely degrading?
How quickly is degradation progressing?
How much useful life may remain?
Is intervention required during the next available maintenance window?
Which assets should maintenance teams inspect first?
This means predictive maintenance can range from relatively simple condition monitoring to sophisticated Remaining Useful Life (RUL) estimation and maintenance optimization.
Predictive vs preventive vs condition-based vs reactive maintenance
Strategy | Trigger | Main advantage | Main limitation |
|---|---|---|---|
Reactive maintenance | Asset has already failed | Simple | Downtime is uncontrolled |
Preventive maintenance | Time, cycles or fixed schedule | Easy to plan | Maintenance may happen too early |
Condition-based maintenance | Measured condition exceeds a threshold | Responds to actual condition | Thresholds may detect degradation late |
Predictive maintenance | Estimated future failure or degradation | Creates an earlier decision window | Requires data, models and operational integration |
Prescriptive maintenance | Prediction + optimized recommended action | Supports decision making | More complex architecture and governance |
Predictive maintenance is therefore not simply “maintenance with sensors”.
A temperature threshold that triggers when a motor reaches 90°C is condition monitoring.
A system that combines temperature trends, vibration spectra, load, maintenance history and environmental conditions to estimate increasing bearing-failure risk is much closer to predictive maintenance.
Move from detecting failures to anticipating operational risk
thaink² Predictive Agent helps teams turn operational data into forecasts, anomaly signals and decision-ready insights connected to real business workflows.
How predictive maintenance works
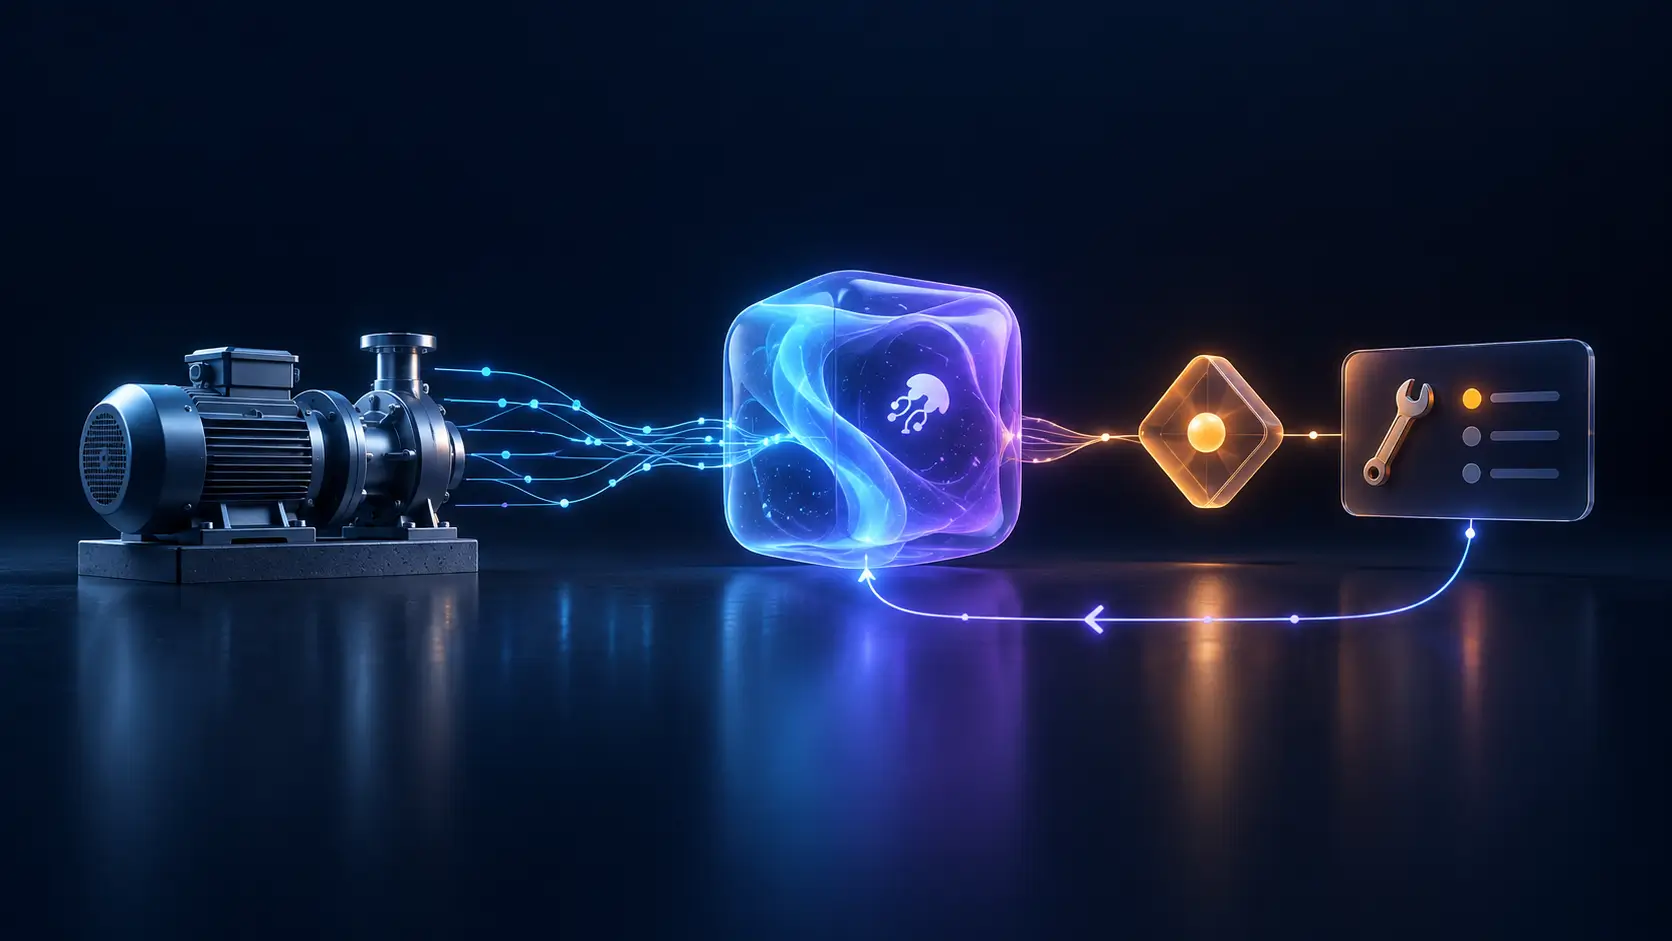
A useful predictive-maintenance system can be understood as a continuous loop:
Each stage matters.
A sophisticated prediction built on unreliable measurements is unreliable.
A perfect anomaly score that never reaches the maintenance team creates no operational value.
And a good alert that arrives only five minutes before catastrophic failure may be technically correct but operationally useless.
1. The asset produces physical signals
Industrial assets continuously generate physical behavior.
Depending on the asset, useful signals may include:
vibration;
temperature;
pressure;
flow;
electrical current;
voltage;
rotational speed;
torque;
acoustic emissions;
lubricant characteristics;
humidity;
machine states;
control-system events.
The relevant signal depends on the expected failure mode.
A vibration sensor can be highly informative for rotating machinery but irrelevant for a failure primarily caused by corrosion or software-controlled process conditions.
2. Signals become usable data
Raw measurements typically need to be synchronized, cleaned and placed in the context of the asset.
This may require combining:
sensor streams;
PLC or SCADA data;
machine logs;
production parameters;
environmental variables;
ERP information;
work orders;
inspection history;
component replacements;
operator notes.
This context matters because an increase in vibration may be abnormal at one operating speed and completely normal at another.
3. Features or representations are created
Classical systems often derive engineered features such as:
RMS vibration;
kurtosis;
spectral peaks;
temperature gradients;
pressure variance;
moving averages;
rate of change;
cycle counts.
Deep-learning systems may learn representations directly from raw or minimally processed signals.
Neither approach is universally superior.
The choice depends on available data, sampling rate, interpretability requirements, model complexity and the physics of the failure.
4. The model estimates condition or future risk
The model may attempt to:
detect an anomaly;
classify a fault;
estimate failure probability;
estimate degradation state;
predict Remaining Useful Life;
forecast a sensor or health indicator.
5. The prediction becomes an operational decision
This stage is often ignored in AI demonstrations.
A model output such as:
failure probability = 0.73
does not tell a maintenance planner what to do.
A production system needs to combine model output with operational context:
asset criticality;
spare-part availability;
maintenance capacity;
production schedule;
safety consequence;
redundancy;
inspection cost;
lead time.
Predictive maintenance creates value when the prediction changes a decision.
The industrial AI architecture behind predictive maintenance
Layer 1 — Asset and sensor layer
The physical environment generates the signals.
This can involve existing instrumentation or additional sensors installed for a specific failure mode.
Common sources include:
Vibration sensors
Bearing, motor, gearbox, pump and rotating machinery monitoring.
Temperature sensors
Motors, electrical equipment, furnaces, bearings and lubrication systems.
Current and voltage measurements
Electrical motors, drives and power systems.
Pressure and flow sensors
Hydraulic systems, pumps, compressors and pipelines.
Acoustic and ultrasonic sensors
Leaks, cavitation, friction and mechanical degradation.
Layer 2 — Edge and acquisition
Not every signal should be continuously sent to the cloud.
High-frequency vibration measurements can generate large volumes of data.
Edge processing can:
filter noise;
aggregate measurements;
extract features;
detect obvious anomalies;
reduce bandwidth;
maintain low-latency monitoring.
Edge and cloud are therefore not competitors.
A production architecture often divides responsibilities between them.
Layer 3 — Data platform
The data layer brings together time-series sensor data and business context.
Typical inputs can include:
OT data
PLC, SCADA, historian, sensors.
IT data
ERP, CMMS, inventory, asset registry.
Maintenance data
Work orders, inspections, failures, replacement history.
Operational data
Production speed, load, recipes, shifts, environmental conditions.
Without an asset model linking those sources, the predictive model may know that “sensor 1842” changed but not that sensor 1842 belongs to the drive-end bearing of a compressor that was replaced two months ago.

Layer 4 — Analytics and machine learning
This layer converts the data into information about equipment condition.
Several modeling strategies are possible.
Five AI approaches used in predictive maintenance
1. Anomaly detection
Anomaly detection learns what normal operation looks like and identifies departures from that baseline.
It is useful when failures are rare and labels are scarce.
Examples include:
isolation forests;
one-class SVMs;
autoencoders;
statistical control models;
reconstruction-error models.
Its main advantage is that it can often be developed without thousands of historical failures.
Its main limitation is equally important:
an anomaly is not necessarily a failure.
A new operating regime can appear abnormal without being dangerous.
2. Failure classification
If historical failures are sufficiently labeled, supervised learning can classify fault types.
Potential models include:
logistic regression;
random forests;
gradient boosting;
support vector machines;
neural networks.
For example, a model may distinguish between:
bearing wear;
imbalance;
misalignment;
cavitation;
lubrication problems.
The bottleneck is often not algorithm selection.
It is the quality of failure labels.
3. Failure-probability prediction
Instead of classifying the current state, the model estimates the probability that a failure will occur within a specific horizon.
For example:
Probability of pump failure within 72 hours: 18%.
This formulation is often easier to integrate into risk-based maintenance planning.
4. Remaining Useful Life estimation
RUL models estimate how much useful operating life remains before a component reaches a failure condition.
This is especially useful when maintenance decisions require lead time for:
spare parts;
crew scheduling;
production shutdowns;
logistics.
5. Forecasting degradation
Instead of predicting failure directly, a model may forecast the future evolution of a health indicator.
For example:
current vibration trend → expected threshold crossing in 11 days
This can be useful when degradation evolves continuously.
Why predictive-maintenance data is unusually difficult
Industrial machine-learning datasets have an uncomfortable characteristic:
most of the data represents healthy machines.
Failures are rare.
That is good operationally.
But it creates a machine-learning problem.
A dataset may contain:
millions of normal observations;
a few hundred degraded observations;
ten actual failures.
A naïve classifier can reach extremely high accuracy simply by predicting “healthy” all the time.
This is why accuracy alone is usually a poor metric.
Teams may instead evaluate:
precision;
recall;
F1;
false-alert rate;
missed-failure rate;
lead time;
precision-recall curves;
cost-weighted metrics.
The metric that matters most: actionable lead time
Imagine two models.
Model A predicts a bearing failure five minutes before it happens with 99% confidence.
Model B identifies the degradation five days earlier with 85% confidence.
For maintenance planning, Model B may be vastly more useful.
A predictive system needs enough time for the organization to:
inspect the asset;
validate the signal;
obtain a spare part;
schedule personnel;
select a maintenance window;
intervene without disrupting production.
The useful metric is therefore not merely:
Did we predict the failure?
It is:
Did we predict it early enough to change the operational outcome?
Predictive maintenance use cases in industry
Manufacturing
Typical assets:
CNC machines;
motors;
conveyors;
pumps;
gearboxes;
compressors;
robots;
presses.
Possible signals include vibration, current, temperature, cycle time, torque and machine states.
The typical objective is to detect degradation before it interrupts production.
Energy and utilities
Typical assets include turbines, transformers, generators, pumps, substations and wind turbines.
Predictive maintenance can support condition monitoring across assets where failure may involve both downtime and significant safety or reliability consequences.
Oil and gas
Common targets include compressors, pumps, pipelines, turbines and drilling equipment.
Typical data sources include SCADA plus sensor data such as vibration, temperature, pressure and acoustic measurements.
Transportation and fleets
Potential applications include engines, braking systems, batteries, transmissions and rail equipment.
Here the maintenance decision can also incorporate route, mileage, environmental conditions and vehicle utilization.
Aerospace
Predictive systems can support monitoring of engines, hydraulic systems, avionics and structural components.
Explainability and safety requirements are especially important because maintenance decisions may be subject to strict regulatory and engineering constraints.
Process industries
Chemical, pharmaceutical, food and materials-processing environments may use predictive monitoring for pumps, valves, mixers, heat exchangers and compressors.
Predictive maintenance examples by failure mode
The most useful way to design a program is often failure-mode first, not algorithm first.
Asset | Failure mode | Possible signals | Possible model output |
|---|---|---|---|
Bearing | Wear | vibration, temperature | anomaly / RUL |
Pump | Cavitation | vibration, pressure, flow | fault classification |
Motor | Electrical degradation | current, temperature | failure probability |
Compressor | Seal degradation | pressure, temperature | anomaly |
Gearbox | Tooth wear | vibration, acoustic | fault classification |
Battery | Capacity degradation | voltage, current, temperature | RUL |
Valve | Leakage / stiction | pressure, position | anomaly |
Turbine | Mechanical degradation | vibration, temperature | RUL / failure risk |
The important distinction is that the model must connect to a specific physical or operational hypothesis.
“Apply AI to our factory” is not a predictive-maintenance use case.
“Detect bearing degradation on the three compressors responsible for 40% of critical-line downtime” is.
From predictive to prescriptive maintenance
Predictive maintenance asks:
What is likely to happen?
Prescriptive maintenance asks:
What should we do about it?
That requires additional context.
Suppose the model predicts that a pump has approximately seven days of remaining useful life.
The best action depends on:
production requirements;
availability of a backup pump;
technician schedules;
spare inventory;
cost of shutdown;
probability uncertainty;
safety risk.
This is where predictive systems begin to evolve from dashboards into decision infrastructure.
A prediction only matters when it changes the maintenance decision
Connect forecasting, anomaly detection and operational context so maintenance teams can prioritize the right intervention instead of reviewing another isolated AI score.
How to implement predictive maintenance step by step
Step 1 — Start with asset criticality
Do not instrument the entire factory.
Rank assets according to:
downtime consequence;
failure frequency;
repair cost;
safety impact;
replacement lead time;
redundancy.
The best pilot is rarely the machine with the most sensors.
It is the asset where an earlier warning would actually create measurable value.
Step 2 — Select one or two failure modes
A useful pilot should answer a precise problem.
For example:
Detect early bearing degradation in compressor family X.
This defines which sensors matter, what historical events matter, how much warning is useful and what action should follow.
Step 3 — Audit existing data
Before buying sensors, inspect what already exists.
Sources may include PLC, SCADA, historian, CMMS, ERP, existing sensors, maintenance records and quality systems.
Industrial organizations often already possess valuable signals but have not linked them together.
Step 4 — Instrument only the missing signal
Sensor deployment should be failure-mode driven.
Ask:
Which physical phenomenon changes when this component begins to degrade?
Then measure that phenomenon.
More sensors are not automatically better.
Step 5 — Build a baseline
Before training sophisticated AI, understand normal operation.
Segment behavior by machine, product, speed, load, shift, season and environmental condition.
What looks abnormal globally may be perfectly normal within one operating regime.
Step 6 — Create an evaluation dataset
Separate the production question from the training dataset.
Your evaluation set should represent actual operational questions:
Did the model catch known failures?
How early?
How many false alerts?
Does performance change by asset?
Does it work during different loads?
Does it degrade after maintenance?
Step 7 — Establish a simple baseline model
Do not begin with the most complex architecture available.
Compare advanced models against threshold rules, moving averages, statistical control limits, simple regression and tree-based models.
If the advanced model cannot outperform the baseline in operational value, it should not go into production.
Step 8 — Integrate the prediction into the workflow
Define explicitly:
Who receives the alert?
What information do they see?
What action can they take?
Does an inspection create a work order?
Can the system connect to the CMMS?
What happens if the alert is ignored?
Predictive maintenance implementation is as much a workflow-integration problem as a modeling problem.
Step 9 — Run in shadow mode
Before automatically changing maintenance schedules, run the model alongside the existing process.
Compare predictions, inspections, technician feedback and actual failures.
This allows the organization to calibrate trust without introducing unnecessary operational risk.
Step 10 — Scale only after proving economics
Expand by failure mode, asset family, production line or facility.
Avoid rebuilding a separate model stack for every machine if asset families can share representations or pipelines.
How to calculate predictive-maintenance ROI
The economic case should be defined before the model.
Avoided downtime
Expected downtime avoided × cost per hour
Avoided catastrophic failures
Expected reduction in major failures × average failure cost
Maintenance efficiency
Compare emergency labor, unnecessary preventive intervention, technician utilization and overtime.
Spare-parts optimization
Earlier warnings can improve planning and reduce expedited procurement or excessive inventory.
Asset utilization
A better estimate of equipment condition can prevent both premature maintenance and excessive run-to-failure behavior.
Program cost
Include sensors, connectivity, storage, engineering, model inference, integration and maintenance of the predictive system itself.
Do not evaluate the AI model independently of these costs.
The false-positive problem
A predictive-maintenance system can fail even while detecting many real problems.
Imagine a plant with 200 assets.
If the model generates ten unnecessary alerts per day, technicians may quickly stop trusting it.
This creates alert fatigue.
The objective is not maximum sensitivity.
It is an acceptable trade-off between missed failures, false alerts, warning lead time, inspection workload and failure consequence.
Different assets should therefore have different thresholds.
A low-cost redundant fan and a safety-critical compressor should not share the same decision policy.
Model drift in industrial environments
Machines change.
Bearings are replaced.
Control logic changes.
Production recipes change.
Sensors age.
Factories alter operating schedules.
As a result, the data distribution observed six months after deployment may differ significantly from training.
Monitoring should therefore include:
feature distributions;
anomaly-score distributions;
model confidence;
false-positive rates;
missed events;
sensor health;
equipment configuration.
Every major maintenance intervention can effectively create a new machine state.
Predictive maintenance and digital twins
Digital twins can enrich predictive maintenance by linking real measurements with a dynamic representation of an asset or process.
A predictive-maintenance digital twin may incorporate geometry, engineering constraints, asset state, sensor streams, simulation and degradation models.
The concept is promising, but a digital twin should solve a concrete operational problem rather than become an expensive visualization layer.
Where generative and agentic AI actually fit
Large language models should not replace condition-monitoring models simply because generative AI is fashionable.
LLMs are generally not the right primitive for analyzing raw 20 kHz vibration signals.
Their value sits elsewhere.
An AI agent can:
retrieve maintenance procedures;
inspect work-order history;
query asset data;
request a predictive model score;
compare similar historical incidents;
explain the alert;
propose inspection steps;
create a draft work order;
escalate to a human.
This creates a useful separation:
specialized predictive models detect physical degradation
while
agents orchestrate information and decisions around the prediction.
What not to do
Do not start by buying sensors for every machine
Start with failure modes and economic value.
Do not optimize model accuracy in isolation
Optimize operational decisions.
Do not confuse anomalies with failures
Not every unusual behavior requires maintenance.
Do not ignore maintenance history
Sensor data without intervention context can be misleading.
Do not automatically act on every model output
Use human review where consequences justify it.
Do not scale a pilot before measuring value
A successful notebook is not a successful maintenance program.
A predictive-maintenance readiness checklist
Business
Is the asset economically important?
Is unplanned failure materially costly?
Would earlier warning change the decision?
Failure mode
Is the failure mechanism understood?
Is there a detectable degradation period?
How much warning time is useful?
Data
Are relevant measurements available?
Is sampling frequency sufficient?
Can maintenance records be linked to assets?
Are failure labels trustworthy?
Architecture
Can signals be ingested reliably?
Is edge processing required?
Can predictions reach the CMMS or ERP?
Evaluation
What is the acceptable false-positive rate?
How will missed failures be measured?
How much lead time is required?
Operations
Who owns the alert?
Who validates it?
What action follows?
How is the outcome fed back?
If these questions cannot be answered, the organization may not need a more advanced model yet.
It may need a better maintenance-data foundation.
Predictive maintenance best practices
Start narrow.
One critical asset family and one valuable failure mode.
Use physics as context.
Machine learning should complement engineering understanding.
Benchmark simple approaches.
Do not assume deep learning is necessary.
Evaluate on time, not random rows.
Random train/test splits can leak information between nearby observations.
Optimize for lead time.
A warning needs to arrive early enough to act.
Measure false alerts.
Technician trust is part of system performance.
Preserve asset history.
Repairs and replacements change the meaning of future signals.
Connect to maintenance workflows.
Predictions should reach the system where work is actually managed.
Monitor after deployment.
Industrial conditions drift.
Retain human oversight for consequential decisions.
Where thaink² fits
thaink² should not be positioned as a sensor manufacturer or a generic CMMS replacement.
The value sits in the analytical and agentic layer between operational data and business decisions.
The Predictive Agent can serve as the decision layer around predictive workflows by connecting forecasts, anomalies and operational context to the people or systems that need to act.
For dedicated industrial predictive-maintenance use cases, the AI Predictive Maintenance solution can connect:
while other thaink² agents can complement the workflow.
A Knowledge Agent may retrieve equipment procedures.
A Data Analyst Agent may investigate recurring failure patterns.
An agentic layer may orchestrate these capabilities without requiring one model to solve every problem.
Turn industrial data into earlier, better operational decisions
Build predictive workflows that connect machine signals, analytics and business context instead of leaving predictions isolated in another dashboard.
The practical takeaway
Predictive maintenance is not a machine-learning model attached to a machine.
It is a decision system.
The complete chain is:
If one link fails, the business value disappears.
The strongest industrial implementations therefore do not begin with:
Which AI model should we use?
They begin with:
Which failure do we need to see earlier, how early must we see it, which signal reveals it, and what will we do differently when we know?
Everything else should follow from that decision.
Faq
What is predictive maintenance in industry?
Predictive maintenance uses equipment-condition and operational data to estimate degradation or failure risk before breakdown occurs, helping maintenance teams decide when intervention is actually required.
How does AI improve predictive maintenance?
AI and machine learning can detect anomalies, classify faults, estimate failure probability, forecast degradation and predict remaining useful life from sensor and operational data.
What sensors are used for predictive maintenance?
Common sensors measure vibration, temperature, current, voltage, pressure, flow, acoustic emissions, speed and lubricant condition. The right sensor depends on the physical failure mechanism.
How do you implement predictive maintenance?
Start with a critical asset and specific failure mode, audit existing data, instrument missing signals, establish a baseline, evaluate models against operational metrics, integrate predictions into the maintenance workflow, pilot in shadow mode and scale only after proving value.
What is the difference between preventive and predictive maintenance?
Preventive maintenance is triggered by fixed schedules or usage intervals. Predictive maintenance uses actual equipment condition and behavior to estimate future degradation and determine when intervention is likely to be necessary.
Sources link
Springer: AI-driven predictive maintenance architecture
ScienceDirect: Dynamic predictive maintenance and Remaining Useful Life
Scientific Reports: class imbalance in predictive maintenance
ScienceDirect: explainable predictive maintenance for safety-critical equipment
MDPI: digital twins for predictive maintenance
Journal of Manufacturing Systems: agentic AI for prescriptive maintenance

