Jev is TypeSafe AI’s first public System One Model: a model built to return typed probabilistic decisions instead of open-ended text. This guide explains how Jev works, Noul, Choice and Score, its differences from LLMs and classifiers, enterprise use cases, limitations and how to evaluate it in production.


Jev is not another chatbot model.
TypeSafe AI introduced Jev as the first public example of what it calls a System One Model: a model designed to make bounded, typed decisions inside software rather than generate open-ended prose for a person to read.
That distinction sounds small until you look at the interface.
A traditional large language model is usually asked to produce tokens that eventually become text, JSON, code or tool arguments. Jev is designed around a different contract:
The application can then use those decisions directly in code.
That makes Jev interesting for routing, classification, ranking, escalation, policy checks, tool selection and other narrow decisions that appear repeatedly inside AI agents and enterprise workflows.
It does not make Jev a replacement for every LLM.
The more useful way to think about it is as a specialized decision layer that can sit beside deterministic code, retrieval systems, tools and generative models.
This guide explains what Jev is, how TypeSafe’s System One concept works, how its Noul, Choice and Score primitives differ, where Jev fits inside an AI-agent architecture, how it differs from JSON-mode LLMs and classifiers, what its current limitations are, and how enterprise teams should evaluate it before production use.
What is Jev AI?
Jev is TypeSafe AI’s first public System One Model, built to return typed probabilistic decisions rather than free-form generated text.
TypeSafe released Jev publicly in September 2026 and describes it as a model optimized for automation inside software. Its public API accepts a state plus one or more typed questions and returns answers that software can consume programmatically.
According to TypeSafe’s API documentation, the supplied state can be a string, object or array. Questions can use different primitives in the same request, and the response associates each answer with the corresponding question.
The important architectural shift is that the model is not being asked to write an explanation of what should happen. It is being asked to decide among explicitly defined outcomes.
What is a System One Model?
“System One Model” is TypeSafe AI’s own category name for models optimized for fast, structured decisions that can be embedded directly into software workflows.
The terminology borrows from the familiar distinction between fast, intuitive decisions and slower, deliberative reasoning, but it should not be treated as an established industry standard yet. At the time of writing, “System One Model” is primarily a TypeSafe-defined product and research category.
Dimension | System One model such as Jev | General-purpose LLM |
|---|---|---|
Primary output | Bounded typed decision | Generated token sequence |
Typical consumer | Application code | Human or downstream parser |
Best suited to | Classification, scoring, routing, selection | Writing, reasoning, synthesis, coding |
Output space | Explicitly constrained | Potentially very large |
Uncertainty | Probability / confidence is part of the interface | Usually requires separate interpretation or scoring |
Free-form prose | Not the core use case | Core capability |
The useful insight is not that one architecture is universally superior. It is that different parts of an AI system may require different kinds of intelligence.
Separate reasoning from bounded operational decisions
thaink² helps enterprise teams design agent workflows where models, tools, business rules and human escalation each have a clearly defined role.
How Jev works
At a high level, a Jev request contains three things: state, one or more typed questions, and the model to use.
The pattern can be represented as:
state + typed questions → Jev → typed answers + probability information
TypeSafe’s public API exposes three main question families: Noul, Choice and Score. These primitives move part of the workflow policy out of a long natural-language instruction and into an explicit typed contract.
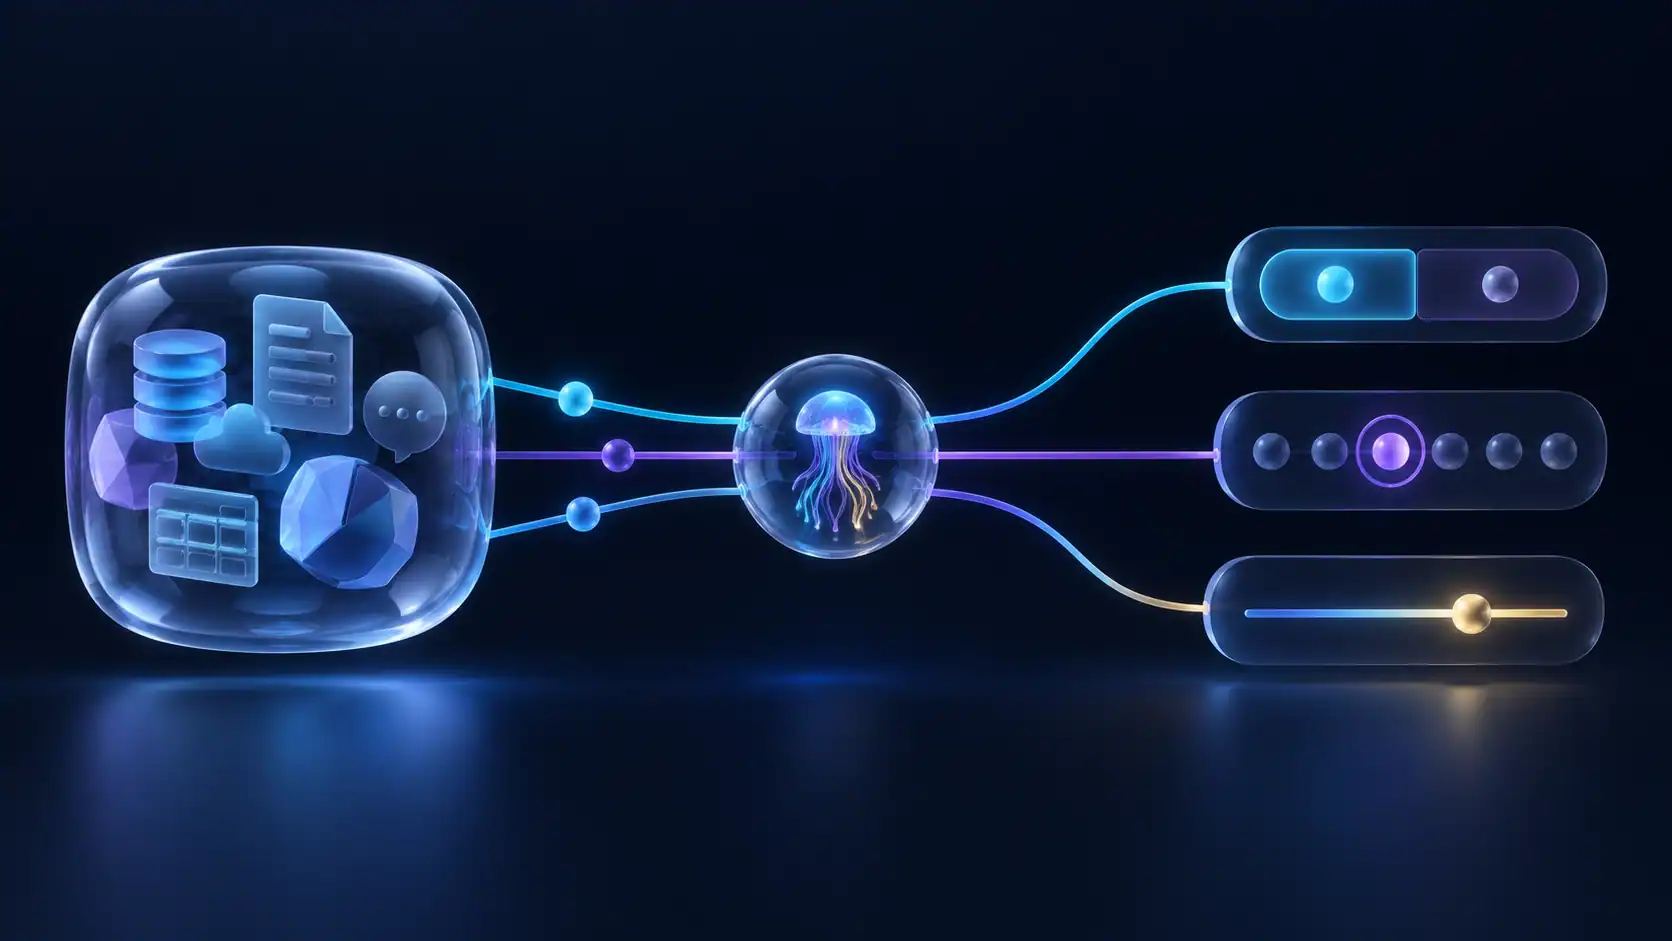
The three Jev primitives: Noul, Choice and Score
Noul: a probabilistic yes-or-no decision
Noul represents a binary judgment. Examples include whether a support conversation requires human review, whether an invoice conflicts with a purchase order, or whether an agent trace shows a likely policy violation.
The model can return a probability rather than pretending every semantic judgment is perfectly certain. That allows application code to define explicit automation and escalation thresholds.
Choice: select one option from a defined set
Choice is useful when the software already knows the valid actions and the model’s role is to select among them: route to Billing, Technical Support, Sales or Human Review; select a tool; or choose the next workflow branch.
TypeSafe describes Choice as returning a distribution across the allowed choices together with confidence information, making it possible to distinguish decisive selections from borderline ones.
Score: rate something on a scale
Score represents an ordered or continuous judgment: urgency, document relevance, action risk or agent-output quality. TypeSafe’s evaluation documentation describes Score as returning a score, a distribution over levels and confidence.
Why typed decisions matter
In ordinary LLM integration, teams often build a pipeline like prompt → generated text → parser → validation → retry → application action.
Structured-output modes improve this substantially, but the application is still using a generative model whose capability surface is much larger than the bounded decision required.
Jev’s thesis is that many automation steps should instead look like state → bounded judgment → typed value → application action.
This reduces the need to parse arbitrary prose, normalize labels, extract a decision from an explanation or place application policy inside one giant prompt.
The boundary between model judgment and deterministic business logic also becomes clearer. That boundary matters for production agents. In our guide to designing an agent runtime for enterprise workflows, we explain why models, tools, state and execution need explicit runtime boundaries.
Jev vs JSON mode and structured LLM outputs
If GPT, Claude or another LLM can already return JSON, why use Jev?
Question | Structured-output LLM | Jev |
|---|---|---|
Can the output match a schema? | Yes | Yes, within its decision interface |
Can it write free-form explanations? | Yes | Not the core design |
Can it solve open-ended reasoning tasks? | Yes | Not the intended use case |
Is the decision space explicitly bounded? | Only if the developer constrains it | Core design principle |
Are probabilities first-class outputs? | Not generally equivalent to calibrated decision probabilities | Core part of the interface |
Best fit | Reasoning plus structured generation | Narrow machine-consumed judgments |
A structured-output LLM remains the stronger choice when a task requires both reasoning and rich generated content. Jev becomes interesting when the prose is unnecessary and the application only needs a bounded decision.
A critical nuance: schema reliability is not decision correctness
TypeSafe has used strong language around Jev and hallucinations. That claim needs careful interpretation.
TypeSafe’s current site clarifies that its “0% hallucination” framing refers to the guarantee that outputs match the defined schema. It is not an observed error rate proving that every decision is correct.
A model can return a perfectly valid typed value and still select the wrong option.
Enterprise teams should separate structural failure from decision failure. Jev’s typed interface can reduce the first class. It does not remove the second.
This is why AI observability and evaluation remain necessary even when outputs are strictly typed.
What does calibrated confidence mean?
Confidence becomes valuable only when it is calibrated enough to drive policy. In a well-calibrated system, decisions assigned approximately 80% probability should be correct roughly 80% of the time across a sufficiently comparable evaluation set.
Teams should not assume that a confidence number is trustworthy simply because an API returns one. Measure calibration on your own domain and map confidence bands to business risk.
Confidence region | What to measure | Potential policy |
|---|---|---|
Low | Observed accuracy and ambiguity | Human review or fallback |
Medium | Errors by decision type | Low-impact automation only |
High | Calibration and rare severe failures | Broader automation if validated |
The exact thresholds should come from the consequence of being wrong, not from a universal default.
Jev vs a dedicated classifier
A dedicated classifier may still be better when labels are stable, you have a large high-quality labeled dataset, latency requirements are extremely strict, the input distribution is narrow or you need full control over training and deployment.
Jev is more attractive when the decision requires semantic understanding but the output must stay bounded—for example interpreting a support conversation, evaluating an agent trace, comparing an invoice with supporting context or routing an ambiguous natural-language request.
The real design space is often deterministic code vs classifier vs decision model vs generative LLM, not merely Jev vs LLM.
Jev vs rule-based systems
Deterministic rules remain the best tool for deterministic policy. If an invoice above €50,000 always requires approval, write that rule in code.
Decision models become useful where the condition itself is semantic or fuzzy. The strongest workflow often combines code for what can be explicit + model judgments for what requires interpretation.
TypeSafe’s own workflow evaluations use this decomposition principle: programmatic rules where possible and narrow model questions where semantic judgment is necessary.
Where Jev fits inside an AI agent architecture
Jev becomes most interesting when viewed as one component inside an agent runtime rather than as a standalone chatbot.
A production agent may need to decide which workflow should handle a request, which tool is relevant, whether retrieval is required, whether an action is risky, whether human review is necessary, or whether a final result meets a quality criterion.
These are not all generation problems.
A possible architecture is request → decision layer → route → tool / retrieval / LLM → evaluation → accept, retry or escalate.
Jev could occupy one or more bounded decision steps in that graph. This complements the broader orchestration layer described in our AI Agent Orchestration solution.

8 practical Jev use cases for AI agents and enterprise software
1. Intent routing
Classify an incoming request into a bounded set of workflows such as billing, support, sales, cancellation or human review.
2. Tool selection
Choose the most appropriate tool when several tools can operate on semantically similar requests.
3. Human escalation
Estimate whether a case requires human review based on ambiguity, risk or policy criteria, then feed that probability into an explicit escalation threshold.
4. Agent trace evaluation
Evaluate a completed agent run for policy adherence, task completion, unexpected tool use or need for manual review. TypeSafe’s public workflow evaluations include an Agent Trace Observability example, making this one of the clearest overlaps with AI Agent Observability.
5. Retrieval relevance scoring
Score whether a retrieved passage is relevant enough to enter final context. This does not replace retrieval; it can act as a post-retrieval judgment layer.
6. Policy classification
Determine which policy category applies before deterministic business rules execute.
7. Risk triage
Estimate urgency or risk before choosing an action path. High-stakes workflows still need stronger controls and human oversight.
8. Output evaluation
Score whether a generated result satisfies defined criteria before release, separating generation from evaluation.
Where Jev is not the right tool
Long-form writing
Jev is not designed to produce articles, reports or conversational prose.
Open-ended reasoning
If a task requires constructing a long argument or solving a complex problem step by step, a reasoning-oriented LLM is a more natural fit.
Code generation
A coding model should generate implementation. Jev may still help decide which code path or tool is appropriate.
Deterministic rules
Do not replace explicit known policy with probabilistic inference.
Irreversible high-stakes decisions without safeguards
Typed output does not make a model infallible. Financial, legal, security, medical or similarly consequential decisions may require human review and domain-specific validation.
Jev performance, cost and latency: what is actually known?
TypeSafe markets Jev around low cost, low latency and performance on bounded decision workflows.
Current TypeSafe pricing lists Jev input at $0.042 per million input tokens with free output. Pricing is time-sensitive and should be verified before production planning.
TypeSafe’s benchmark site reports workflow-level comparisons against other models, but those are vendor-produced results and should be reproduced on your workload rather than treated as universal proof.
Independent testing is beginning to appear. Preuve AI reported 384 yes/no decision calls on a synthetic multilingual classification task, with a median request time of 273 ms in its environment and 326 correct answers among 332 calls it classified as sure. That is useful evidence for one narrow workload, not a universal performance estimate.
The practical conclusion is that Jev’s economics are promising enough that teams with large volumes of bounded semantic decisions should benchmark it against their current stack.
How to evaluate Jev for your own workflow
Step 1 — Define the decision contract
Write down the state available at decision time, allowed outputs, what uncertainty means, what happens when confidence is low and what action follows each outcome.
Step 2 — Build a representative evaluation set
Include easy cases, ambiguous cases, rare edge cases, malformed inputs where relevant and cases where escalation is correct.
Step 3 — Compare against real alternatives
Benchmark current rules, your existing LLM prompt, a structured-output LLM, a dedicated classifier when available and Jev.
Step 4 — Measure more than accuracy
Measure precision, recall, confusion matrix, calibration, uncertainty rate, latency distribution, cost per decision, failure severity and model-version stability.
Step 5 — Treat thresholds as policy
A confidence threshold determines who or what is allowed to act. Thresholds should be derived from risk and empirical calibration, not copied from a generic example.
Step 6 — Re-evaluate after every meaningful change
Model version, question wording, state format, label set and upstream data changes can all alter behavior.
This is exactly why an operational layer matters. See Why Enterprise AI Needs an Operational Layer for the broader argument around monitoring, evaluation and controlled execution.
Make model decisions measurable before they become automation
thaink² AgentOps helps teams evaluate production agents, monitor execution behavior and understand how model and workflow changes affect outcomes over time.
A decision-model production checklist
1. Scope
Is the decision narrow enough to define explicitly?
Are the allowed outcomes bounded?
Should the decision be probabilistic at all?
2. Evidence
Does the state contain what is necessary to decide?
Are permissions or business context missing?
Could stale data change the correct outcome?
3. Evaluation
Do you have representative labeled examples?
Have you measured false positives and false negatives separately?
Have you tested confidence calibration?
4. Policy
What happens below the threshold?
Which outcomes require human approval?
Which deterministic rules override the model?
5. Observability
Can you reconstruct state and answer?
Can you measure by model version?
Can production failures become regression tests?
6. Change management
Can you shadow-test a new Jev version?
Can you roll back?
Do evaluation results gate the switch?

Jev and AI governance
Typed decisions can improve governance because the action space is explicit, but governance still depends on the surrounding system.
Teams need to know which model made the decision, which state it received, which choices existed, what confidence was returned, which threshold converted the judgment into action, whether a human could override it and what happened afterward.
A bounded model interface can make a system easier to control, but it does not define an organization’s acceptable risk.
For a broader framework, see What is an agentic AI governance framework and how should enterprise teams use one?
Jev and AgentOps
Decision models make observability more structured, not less necessary.
Teams can monitor choice distribution, confidence distribution, escalation rate, false-automation rate, disagreement with humans, decision latency, cost per thousand decisions and regressions after model updates.
Our AgentOps guide explains how monitoring, evaluation and usage visibility fit around production agents.
The most useful architecture may combine Jev and LLMs
The emergence of decision models does not imply the end of generative models.
This assigns narrower responsibilities and creates cleaner evaluation boundaries: was routing correct, did the tool execute, was the generated answer good, and was escalation applied correctly?
What Jev changes and what it does not
Jev makes one design question explicit: does every intelligent step in software need to be a text-generation problem?
For routing, classification, relevance, risk, tool selection and escalation, often not.
But the surrounding fundamentals remain: good input data, clear task definitions, representative evaluations, permissions, deterministic safeguards, observability, version management and human escalation where appropriate.
A cleaner output contract cannot compensate for an undefined business decision.
Where thaink² fits
thaink² is not tied to one model family. Our focus is the operational layer around enterprise agents: how data, specialized models, tools, workflows, evaluation and supervision fit together.
A decision model such as Jev can be valuable when a workflow contains high-volume semantic judgments with a bounded output space. A generative model may still handle reasoning and content generation. Deterministic code should still own explicit business rules. Retrieval systems should still provide evidence. AgentOps should still measure what happens in production.
The architecture should be designed around the decision, not around loyalty to a particular model.
Design the runtime around the decision, not around one model
Build enterprise agents where routing, tools, generation, evaluation and human review can each use the component best suited to the job.
The practical takeaway
Jev is best understood as a new option in the model stack, not a universal replacement for LLMs.
Its design is compelling when the input requires semantic interpretation, the valid outcomes can be bounded, software needs to act on the result and uncertainty can be incorporated into policy.
If the task is deterministic, use code. If it is a stable supervised classification problem with excellent training data, benchmark a dedicated classifier. If it requires open-ended reasoning or generation, use an LLM. If it is a repeated semantic decision with a constrained action space, Jev is now a model worth testing.
The strategic idea behind System One models may matter more than Jev itself: enterprise AI does not need one model to do everything. It needs clearly bounded intelligence at the right point in the workflow.
Frequently asked questions
What is Jev AI?
Jev is TypeSafe AI’s first public System One Model, designed to take application state and typed questions and return bounded probabilistic decisions that software can act on directly.
What is a System One Model?
System One Model is TypeSafe AI’s term for models optimized for fast, structured decisions inside software rather than open-ended text generation. It is currently a vendor-defined category rather than an established industry standard.
How is Jev different from an LLM using JSON mode?
JSON mode constrains the format produced by a generative LLM. Jev is designed specifically around bounded decision primitives and probability outputs, while structured-output LLMs remain more flexible for tasks that also require reasoning or generated content.
Can Jev make wrong decisions?
Yes. Jev can return a structurally valid typed answer that is semantically wrong. TypeSafe’s schema guarantees do not remove the need for evaluation, calibration testing, thresholds, monitoring and human escalation where appropriate.
What are the best use cases for Jev?
Strong candidate use cases include intent routing, tool selection, classification, human escalation, risk triage, retrieval relevance scoring and agent-output evaluation when the valid action space is bounded.

