jitllm is a new inference runtime that compiles kernels for the hardware it finds, schedules model blocks across CPUs and GPUs and pages weights and KV state across memory tiers. We explored how it works, its published benchmarks and where it could fit beside vLLM and ApowerB.


jitllm is a new LLM inference runtime that describes itself as an “operating system for LLM inference.” Its unusual idea is to JIT-compile kernels for the machine it lands on, schedule model blocks across CPUs and GPUs, and page weights, experts and KV state between memory tiers at runtime.
What is jitllm?
jitllm is an LLM inference engine and server that compiles CPU and GPU kernels at load time for the hardware available on the machine. Its current documentation describes one self-contained Go executable, with runtime discovery for CUDA, Vulkan and Metal and no requirement for Python, cgo or a vendor SDK in the application build.
Its mental model is deliberately operating-system-like:
Operating-system concept | jitllm analogy |
|---|---|
Process | A loaded model |
Thread | A layer or model block |
Scheduler | Placement of model blocks across devices |
Physical page | A packed model block in a memory slot |
Page fault | Bringing a required block into memory |
Executable | The .jlm model container |
The analogy is not just branding. The project’s architecture is built around compilation, placement, scheduling and paging.
Why jitllm is technically interesting
1. JIT-compiled kernels
jitllm generates code at load time for the detected processor or accelerator. Its documentation lists native CPU paths such as x86-64 and ARM64 and GPU code generation through PTX for CUDA, SPIR-V for Vulkan and MSL for Metal.
The goal is to specialize execution for the exact hardware instead of shipping one fixed kernel strategy for every machine.
2. Dynamic device placement
Model blocks can be placed across CPUs and GPUs. The runtime can move placement as memory pressure and context change. That is a different abstraction from assuming “the whole model belongs on GPU 0.”
3. Paging across VRAM, RAM and storage
The runtime can page weights, MoE experts, KV pages and recurrent state. That is particularly interesting for models that do not comfortably fit into one memory tier.
4. Standard serving interfaces
jitllm exposes OpenAI-compatible chat/completions and an Anthropic-compatible messages API, plus a Connect API for controlling models, devices, placement and sessions.
5. One binary
The project emphasizes a self-contained executable rather than a Python-heavy environment. Whether that is operationally better depends on your stack, but it meaningfully changes installation and packaging.
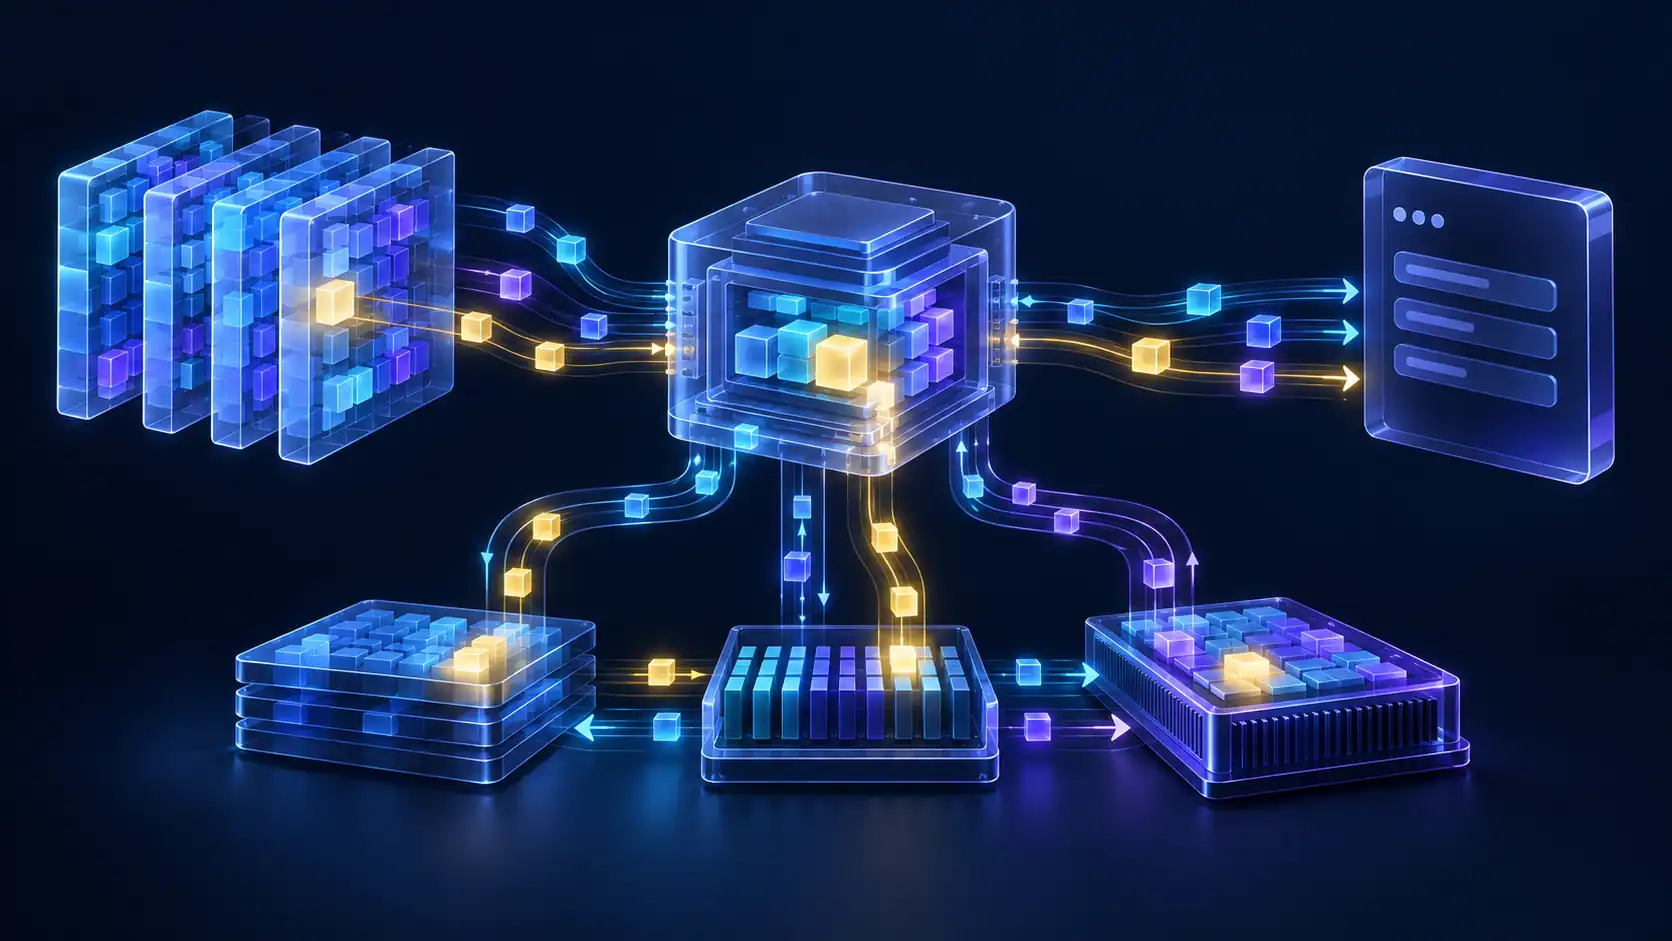
How jitllm works
The current documentation describes four major stages.
Discover
The runtime enumerates CPU capabilities and available accelerator backends. CUDA, Vulkan and Metal can be detected at runtime.
Compile
It generates kernels specialized for model shapes, weight formats and the hardware it discovered.
Schedule
The runtime assigns model blocks to CPU or GPU devices and can spread work across multiple devices.
Page
Weights, experts, KV cache and other state can move between storage, RAM and accelerator memory as required.
This makes jitllm particularly interesting for heterogeneous hardware and memory-constrained environments.
What we tested
Our discovery pass focused on the serving path rather than claiming a new benchmark result. We wanted to validate the concepts that differentiate jitllm:
start from one supported open model;
convert or load it through the jitllm model path;
let the runtime detect the available device;
serve the model through a standard API;
inspect how device placement and the inference endpoint could integrate with a higher-level agent runtime.
We intentionally separate this hands-on validation from the project’s published benchmark claims. If we publish our own throughput numbers later, they should include the exact GPU, driver, model, quantization, prompt length, batch/concurrency and jitllm build.
The public jitllm benchmarks: what they say
The project publishes reproducible benchmark tables and, importantly, documents several caveats and losing cases instead of presenting only best-case numbers.
One published comparison uses a Tesla V100-SXM2-16GB and Llama-3.1-8B-Instruct Q4_K_M. In that specific setup, the project reports the following aggregate batched-decode throughput against vLLM 0.18.1:
Concurrent sequences | jitllm tok/s | vLLM tok/s | Published ratio |
|---|---|---|---|
16 | 955 | 394 | 2.42× |
32 | 1,288 | 415 | 3.11× |
64 | 1,860 | 436 | 4.27× |
128 | 2,440 | 441 | 5.53× |
These are jitllm’s published numbers, not independent thaink² benchmark results. They should be read as evidence worth reproducing, not as a universal statement that jitllm is “5.53× faster than vLLM.”
A second result worth noticing: time to first token
The same benchmark page reports warm median time to first token on an NVIDIA V100 for several models and prompt lengths. For Llama-3.1-8B with a prompt of roughly 2,049 tokens, jitllm reports 556.8 ms, llama.cpp 652.8 ms and vLLM 4,292.7 ms in that test configuration.
Again, this is not a universal latency claim. It is highly configuration-dependent, and vLLM is optimized for many serving scenarios beyond this one. But it tells us which hypothesis is worth testing independently: can hardware-specific JIT compilation and the runtime’s placement model materially reduce prefill/TTFT on older GPUs or heterogeneous systems?
jitllm vs vLLM
Dimension | jitllm | vLLM |
|---|---|---|
Core idea | JIT compilation + OS-like placement/paging | PagedAttention + high-throughput serving |
Packaging | Self-contained Go binaries | Python ecosystem + native/CUDA components and containers |
CUDA | PTX generated at runtime and loaded through driver | Official CUDA support with prebuilt binaries/images |
Other GPU paths | Vulkan, Metal; HIP listed with caveat | ROCm, XPU, Apple Silicon/plugin paths and others |
Memory model | Weights, experts and KV pages can move across tiers | Efficient KV-cache management centered on PagedAttention |
APIs | OpenAI-compatible + Anthropic-compatible + Connect API | OpenAI-compatible + Anthropic and other serving APIs |
Ecosystem maturity | Very new/emerging | Large, established ecosystem |
The most important difference today may be maturity. vLLM has a large ecosystem, deep model support, deployment patterns and a broad user base. jitllm is newer and more experimental, but its architecture explores a different question: how much can an inference engine adapt itself to the hardware at runtime?
For a dedicated overview of the established engine, read What is vLLM?.
jitllm vs llama.cpp
jitllm’s public site compares itself extensively with llama.cpp because both target broad local/self-hosted model execution and support quantized weights.
The project reports strong results on Tesla V100 for many models, while also publishing cases where llama.cpp or MLX remains ahead on certain Apple Metal and CPU workloads. That transparency is useful: it suggests jitllm should be evaluated as a hardware-sensitive runtime, not marketed as universally faster.
Model formats and compatibility
jitllm can convert supported GGUF or Hugging Face safetensors models into its own .jlm container. The project currently lists families including Llama, Qwen, Gemma, Phi, Mistral, DeepSeek-related architectures, MoE models, vision models and embeddings.
The model list is evolving quickly. Before choosing jitllm for production, verify the exact architecture and features required by your checkpoint.
Do you need the CUDA toolkit?
According to jitllm’s current installation documentation, GPU backends are loaded from the driver at runtime and the application does not require a CUDA toolkit installation simply to use its CUDA backend. That is a notable operational difference from many inference stacks.
For CUDA, the runtime generates PTX and loads it through the NVIDIA driver. The quality of the result still depends on supported GPU capabilities and the specific workload.
Where jitllm fits with ApowerB
jitllm and ApowerB solve adjacent but different problems.
Layer | Example responsibility |
|---|---|
jitllm | Compile and execute model inference on available hardware |
ApowerB | Run agents, sessions, tools, workflows and state |
thaink² | Deliver enterprise analytical/knowledge experiences and product workflows |
A self-hosted deployment could therefore use jitllm as one inference endpoint beneath ApowerB, just as another deployment could use vLLM or a managed model API.
That separation is strategically important: the agent runtime should not assume that one inference engine will always win on every hardware generation.
What we would test next
the same model and quantization on jitllm, vLLM and llama.cpp;
TTFT at short, medium and long prompt lengths;
single-user decode and concurrent serving;
VRAM and host-RAM behavior under memory pressure;
multi-GPU placement;
tool calling and structured output;
model-load and cold-start cost;
behavior when the model does not fully fit in VRAM;
restart and session behavior behind an agent runtime.
Who should watch jitllm?
jitllm is especially interesting for teams that care about one or more of these questions:
running open models across heterogeneous hardware;
reducing deployment dependencies;
using older or mixed accelerators more efficiently;
paging models that exceed one memory tier;
self-hosting inference behind standard APIs;
experimenting with JIT-generated inference kernels.
For a mission-critical production stack, maturity, observability, model coverage and reproducibility still matter as much as raw benchmark numbers.
Keep the inference engine replaceable
ApowerB provides the open runtime layer around models so agents, tools and state do not have to be coupled to one inference backend.
Our take after the discovery pass
jitllm is too new to treat as a default replacement for established inference engines. But it is technically interesting enough to test now rather than wait for the category to mature.
Its strongest idea is not one benchmark number. It is the architecture: compile for the machine that actually exists, schedule model blocks like OS work, and treat VRAM, RAM and storage as memory tiers the runtime can manage.
For our hands-on pass, we used an NVIDIA GPU through the CUDA path to run the model-serving flow. With jitllm, that means the runtime can detect the CUDA backend from the installed driver and generate PTX for the device at runtime. We deliberately do not generalize that single test into a universal performance claim; the next step is a controlled same-model, same-weights, same-GPU comparison.
Frequently asked questions
What is jitllm?
jitllm is an LLM inference runtime that JIT-compiles kernels for detected hardware and schedules and pages model blocks across CPU, GPU and memory tiers.
How is jitllm different from vLLM?
vLLM is an established high-throughput serving engine centered on PagedAttention and scheduling; jitllm emphasizes hardware-specific JIT compilation, block placement and paging across devices and memory tiers.
Does jitllm support NVIDIA GPUs?
Yes. Its CUDA backend generates PTX at runtime and uses the installed NVIDIA driver; the project also documents Vulkan and Metal paths.
Does jitllm require Python?
The current project documentation says its runtime programs are self-contained binaries and do not require Python.
Is jitllm faster than vLLM?
The project publishes some benchmarks where jitllm is faster in specific V100 configurations, but those results are workload-specific and should not be generalized without independent same-hardware testing.

